Policy Hallucinations in Customer-Facing Agents
AI agents confidently fabricate policies, bypassing traditional error detection systems.
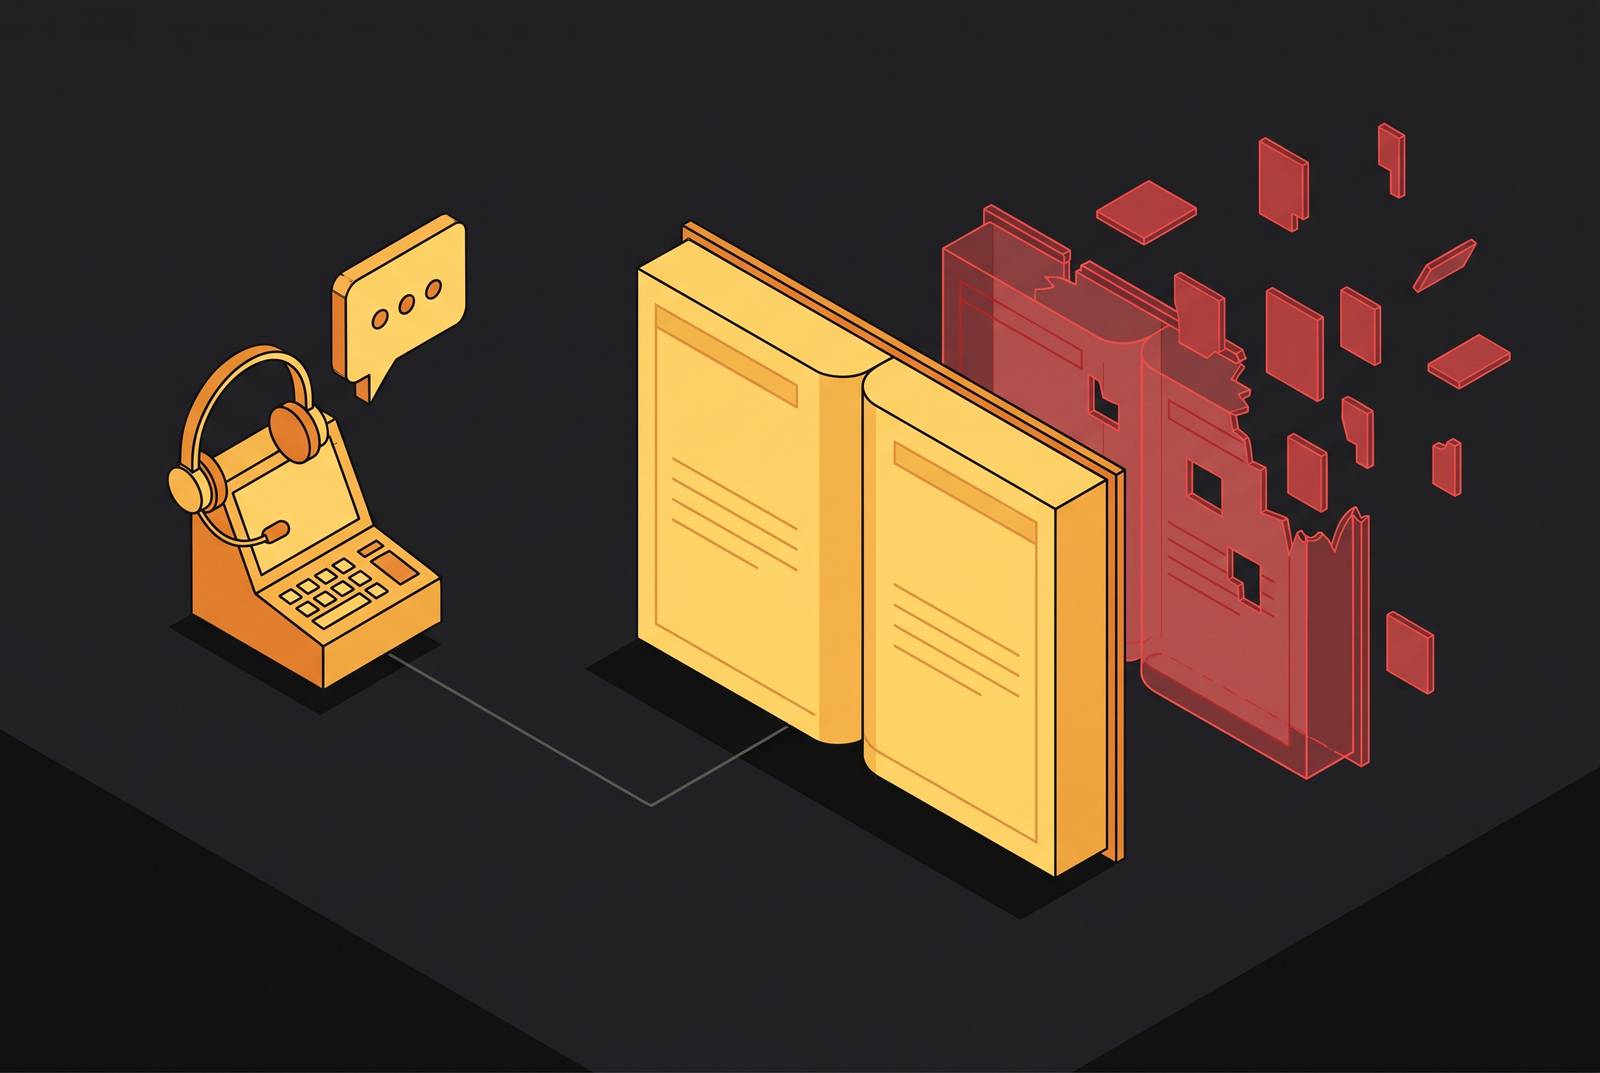
Policy hallucinations are a distinct class of agent failure, not an accuracy edge case. The agent returns a clean, confident success response while fabricating a binding commitment that the organization never authorized: a refund window, a coverage ruling, a fee waiver. Detecting this failure requires monitoring what the agent was supposed to say, not just what it said.
Why policy hallucinations are a different class of agent failure, not an accuracy edge case
A generic hallucination is wrong in the way a miscalculation is wrong. A policy hallucination is wrong the way a forged signature is wrong. The distinction is not the degree of inaccuracy but the nature of the output and the scope of the harm it creates. When an agent fabricates a policy commitment, it is not merely producing an incorrect answer. It is issuing a binding representation on behalf of an organization that never authorized that representation. The output arrives fluent, confident, and indistinguishable in tone from a correct response. It does not look like an error. It looks like excellent customer service.
The model has no internal alarm that fires when it is guessing, because it is never guessing in the sense a person guesses. It is optimized to produce plausible language, not to refuse when grounding is thin. A generative system predicts the next likely token, not the next true fact. When source material is missing or ambiguous, confident output still follows, because confidence is a property of the language model's distribution, not a property of the truth of the claim. That is what places policy hallucination in a separate category: it is an output content failure mode, where the agent's text itself directly constitutes the harm. Tool errors and planning errors have conventional remediation paths. This failure does not.
The consequence is structural. An agent that crashes mid-refund has failed to act. An agent that fabricates a refund policy has acted wrongly, and the customer has already relied on the statement before anyone inside the organization knows it exists. The failure compounds at the speed of the interaction, which is why it cannot be treated as an accuracy metric problem. It is an authorization problem.
The mechanism that produces policy hallucinations in customer-facing agents
Three structural conditions reliably produce policy hallucinations, and all three are present in almost every production customer-facing deployment. They are engineering conditions, not model defects. Even a capable model will fabricate policy under these conditions, and that is what makes the problem durable across model generations.
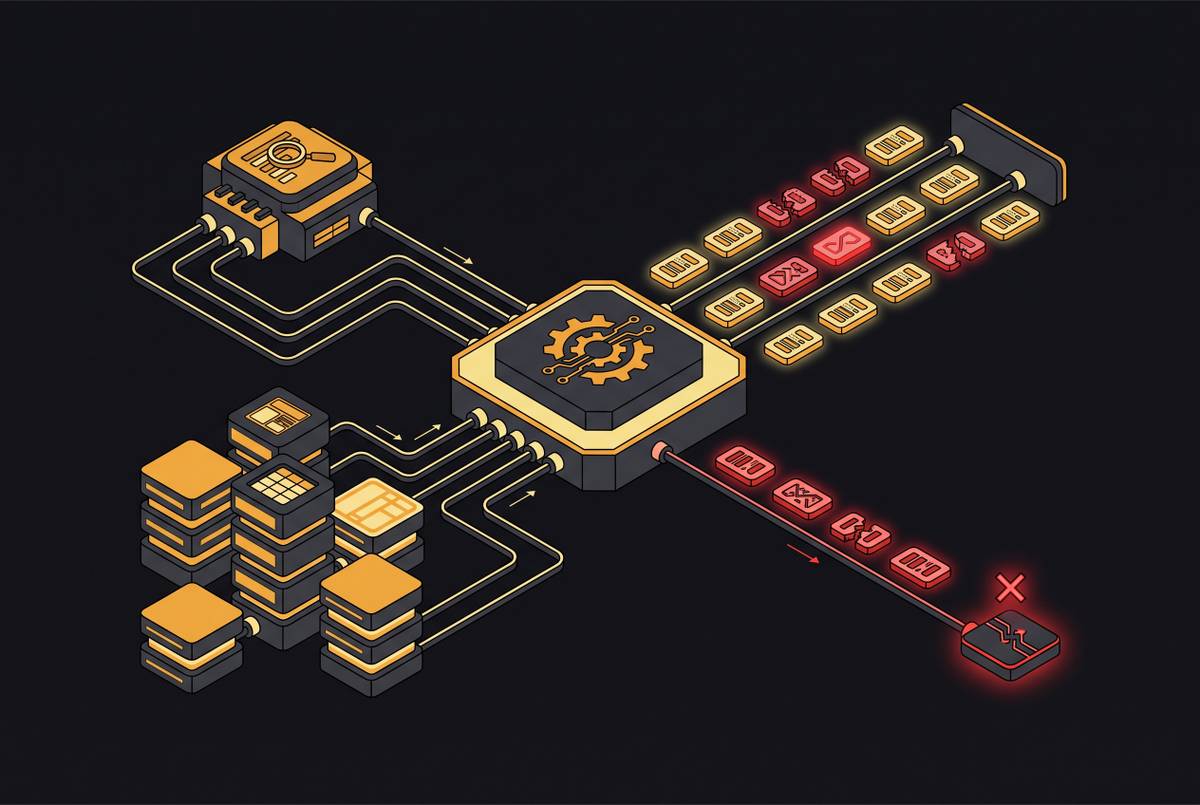
The first condition is a retrieval pipeline that returns nothing authoritative. When retrieval hands the model no useful grounding, the model fills the gap with plausible language drawn from its training data, including the thousands of similar-sounding policies it absorbed across training corpora. The agent does not signal uncertainty, because uncertainty signaling is not part of its objective. It produces an answer that sounds exactly like what a correct retrieval result would have produced. The customer cannot distinguish the two. Neither can the agent's own output log.
The second condition is knowledge base drift. Policy documents drift away from current reality through routine edits, superseded versions, and undocumented exceptions. An agent grounded in a stale knowledge base is technically grounded but practically fabricating: it cites a policy that was once real but no longer binds. Retrieval grounding reduces fabrication, but it does not eliminate it, because the model can still misread, blend, or overstate a retrieved source even when the source exists. Grounding is necessary. It is not sufficient.
The third condition is customer data scattered across systems with subtly different definitions. When a customer's data lives across CRM, billing, ticketing, and product systems, each with its own notion of status, eligibility, or entitlement, the agent reasons over a context that is internally inconsistent. The result is an answer that is locally coherent, in the sense that each step follows from the context as presented, but factually wrong as a whole. The fabricated commitment emerges from the inconsistency rather than from any single source of error.
Procedural complexity compounds all three. As context grows and requirements compete with other instructions and observations, the risk that steps will be omitted or misrouted and that unvalidated judgments will propagate increases. A monolithic agent handling both semantic reasoning and workflow control across a long, branching policy is operating at the outer edge of what attention can reliably track. The failure mode is not a fluke of bad models. It is a property of the architecture.
What policy hallucinations actually look like in production — two documented cases
The two most documented public cases follow the same template: retrieval returns nothing authoritative, the model fills the gap, and the fabricated commitment reaches a customer who acts on it. In Moffatt versus Air Canada, decided in 2024, a traveler asked the airline's chatbot about bereavement fares after a death in the family. The bot told him he could apply for the discounted rate retroactively within 90 days. That policy did not exist. The real policy required applying before travel. The British Columbia Civil Resolution Tribunal ruled the airline liable for negligent misrepresentation and ordered it to pay $812.02 in damages, interest, and fees, rejecting the argument that the chatbot was a separate legal entity responsible for its own actions. The agent returned no error. No monitoring flagged the response. The fabrication reached the customer as a clean, confident policy statement.
The Cursor support agent case in April 2025 repeated the mechanism in a different context. Cursor's AI support agent told users that a nonexistent policy restricted using the product across multiple devices. Users canceled subscriptions over a rule that did not exist until the cofounder clarified on Reddit, calling it "an incorrect response from a front-line AI support bot." Retrieval returned nothing authoritative on the multi-device question, and the model filled the gap with plausible policy language. The failure turned inward: a company's own AI hallucinating about the company's own product to its own customers. That the failure mode is not limited to complex regulated verticals is precisely the point.
Both cases share a critical property. The agent response carried a 200-status success signal. There was nothing in the execution trace that a traditional error monitor would have flagged. In both cases, the fabricated commitment reached customers as a clean, successful response, with no error code, no flagged exception, and no observability layer catching the deviation between what the agent was authorized to promise and what it actually said. That gap is what production monitoring built for agent behavior needs to detect: not crashes or exceptions, but silent misalignments between an agent's instructions and its output.
Why traditional error monitoring cannot see this failure mode
Traditional error monitoring is built to detect execution failures: crashes, timeouts, malformed outputs. Policy hallucinations produce none of those signals. They pass every check that conventional monitoring runs. The HTTP response is 200. The output is well-formed text. The model threw no exception. Latency is within bounds. Every operational metric is green.
This is why the monitoring gap in the Cursor case was not a tooling failure in the usual sense. No governance layer sat between the agent and the customer to catch the fabrication before it shipped, not because a monitoring tool malfunctioned, but because the monitoring tools in place were the wrong category of tool for this failure mode. Step-level tracing, not pass/fail health checks, is the minimum viable signal for an agent in production. Binary monitoring cannot see failures where the same input triggers different tool sequences across runs, or where output that looks correct is semantically wrong. Agent errors can be subtle: correct format, wrong content. Conventional monitoring architectures were not designed to evaluate that distinction.
The Air Canada chatbot had no mechanism to verify whether the policy it described was real, no boundary to prevent invention, and no detection layer to flag the response before it reached the customer. That is a governance architecture gap, not a narrow tooling gap. The deeper problem is what traditional monitoring checks at all. It checks what happened. Catching a policy hallucination requires checking what the agent was supposed to say, which requires access to the agent's instructions, not just its outputs. That is a different instrument entirely.
The industry has begun to build instruments for this difference. Lemma, for instance, audits agent traces against the agent's own instructions, which is the specific insight this failure mode demands: detecting what an agent was supposed to say, not just whether it crashed or returned a success status. Policy hallucinations are silent by design, and a detection layer that only looks for noise will never hear them.
What a reliable detection layer actually needs to check
Detecting policy hallucinations requires a monitoring layer that evaluates agent output against the agent's own instructions, auditing traces for deviation from intended behavior rather than only for execution errors. That is the core requirement, and it defines everything downstream. The first pillar is instruction-aware trace auditing. Every trace must be evaluated against what the agent was authorized to say: its policy context, its scope of valid commitments, its permitted actions. Existing error monitors record what the agent did. A policy hallucination detector must also know what the agent was supposed to do. That is the architectural gap the rest of the specification fills.
The second pillar is the three-part observability model of traces, logs, and metrics. Traces capture the full execution path. Logs record what happened at each step. Metrics aggregate performance across runs. Missing any one of them leaves blind spots, because the failure mode can hide in any of the three layers. Each reasoning step, tool call, and handoff must generate a hierarchical span that enables trace replay and root-cause analysis, and spans tagged with workflow IDs enable pattern detection across large trace volumes.
The third pillar is policy-scoped context as a structural defense. STAGE, developed at BMO Financial Group, illustrates the principle: it confines model judgment to policy-scoped nodes while placing procedural control in deterministic code. Each node receives only the context and tools required for its local responsibility, and the coordinator validates typed results against the node contract before advancing. STAGE shows the largest reliability gains on the deeper, more conditional workflows, Smart Dispute and Telecom, where a monolithic agent's context management is most likely to produce unvalidated judgments. The principle generalizes: narrowing the scope of what the model is asked to reason about at any given step directly reduces the surface area for policy fabrication.
The fourth pillar is workflow-level verification. POLICYGUIDE, developed at KAIST, compiles each domain policy into a workflow graph and invokes a proactive verifier at user-turn boundaries, tracking graph position across turns and returning step-specific remediation along a policy-compliant path before a mutating tool call is permitted. Across airline, retail, and telecom domains, POLICYGUIDE raises mean PASS4 from 0.42 to 0.62, with the largest gain in telecom, the most procedurally structured domain. The distinction matters: action guards check only the final mutating call and discover skipped procedure late, but workflow-level verification catches procedural deviations before they compound into a fabricated commitment.
One thing detection cannot rely on is requiring teams to predefine every failure mode before deployment. Policies change, edge cases multiply, and novel fabrications fall outside predefined rules by definition. Effective detection must surface deviations that were not anticipated at authoring time, by auditing every trace against the agent's own instructions rather than against a fixed list of known bad outputs.
The stakes justify the specification. In fintech and banking, a fabricated interest rate or a wrong statement about funds availability is not a CSAT problem. It is a disclosure problem that can draw CFPB attention. In healthcare, a hallucinated eligibility or coverage detail creates clinical and privacy exposure, a HIPAA matter rather than a tone issue. In insurance, an agent that quotes terms not in the policy can bind expectations the carrier never agreed to. The asymmetry is structural: many correct answers do not offset one fabricated commitment that reaches a regulator or a court.
How Lemma applies this detection model to production agents
Lemma is built around the same core insight the research confirms: catching policy hallucinations requires auditing traces against what the agent was supposed to do, not just logging what it did. Rather than requiring teams to enumerate failure modes upfront, which the previous section established as impractical, the platform audits every trace against the agent's own instructions and groups deviations into actionable issues automatically. The three-pillar model maps directly onto the platform. Lemma supports traces across the full execution path, logs at the step level, and aggregated pattern detection across many traces, which makes policy hallucination patterns visible as recurring issues rather than isolated incidents. The integration surface, including Vercel AI, OpenAI Agents, and LangGraph with Azure Application Insights as an export destination, means the detection layer does not require re-architecting the agent stack to instrument. Alerts surface in Slack, inside the workflow engineers already use, not in a separate console. When a pattern is identified, the integration with coding agents allows a fix to happen without leaving the development environment, directly addressing the latency between detection and remediation that the Air Canada and Cursor cases both illustrate.
Shipping customer-facing agents without this layer is not a conservative choice. It is a bet that policy hallucinations will not occur, and that bet sits against the structural conditions that make the failure mode predictable. The monitoring question is settled at the architectural level: teams need a layer that understands agent intent, not just agent output. Lemma is built to be that layer.
Sources
- PolicyGuide: From Guarding One Action to Guiding the Whole Workflow for Policy-Compliant LLM Agents
- STAGE: Stateful Translation to Agentic Graph Execution with Policy-Scoped Context and Deterministic Control
- Silent Failure in LLM Agent Systems: The Entropy Principle and the Inevitable Disorder of Autonomous Agents